

 Text Annotation
 Audio Annotation
 Image & Video Annotation
 Generative AI, LLM, RAG Data Structuring
 AI Model Development
 In-House Support
 For the medical industry
 For the automotive industry
 For the IT industry
 For the manufacturing industry

For AI and LLMs to understand language naturally like humans and respond appropriately, simply preparing a large amount of text data is not enough. Because language contains ambiguity and diverse meanings, especially in the field of natural language processing (NLP), "text annotation," which adds information such as meaning, intent, and context to text, plays an important role. The data created in this way is used for model training, so the quality of the data greatly affects the accuracy of the model and the quality of its output.
This article provides an organized overview explaining the basic concepts of text annotation, its main types, work processes, and challenges. For details on guideline design, quality control, NER (Named Entity Recognition), and more, please also refer to related articles.
- Table of Contents
-
- 1. What is Text Annotation?
- 1-1. The Role in NLP, Machine Translation, and LLM Development
- 1-2. Differences from Image Annotation and Speech Annotation
- 2. Why is Text Annotation Important?
- 2-1. The Relationship with Fine-tuning and RAG
- 3. Main Types of Text Annotation
- 3-1. Named Entity Recognition (NER)
- 3-2. Part-of-Speech Tagging (POS Tagging)
- 3-3. Sentiment Analysis (Sentiment Annotation)
- 3-4. Intent Recognition (Intent Annotation)
- 3-5. Relation Extraction
- 4. General Workflow of Text Annotation
- 5. Common Challenges and Solutions in Text Annotation
- 5-1. Variability Due to Ambiguity in Judgment Criteria
- 5-2. Balancing Scale Expansion and Quality Maintenance
- 5-3. Issues of Security and Data Management
- 6. Human Science Support for Text Annotation
1. What is Text Annotation?
Text annotation is the process of adding labels or tags to text to organize it in a way that AI models can properly recognize and learn from the data. For example, by using data labeled with named entities such as personal names or organization names for training, AI can learn to identify these entities. Additionally, by training on data labeled with intents such as requests or suggestions, it becomes possible for AI to understand the user's spoken intent.
Through such annotation, AI models can go beyond learning language patterns and also grasp the underlying meanings and contexts. For example, the expression "Otsukaresama desu" can be used not only to convey appreciation but, depending on the situation, also as a greeting or an expression of gratitude. Text annotation plays an important role in enabling the understanding of contextual differences in meaning, contributing to the realization of more natural and human-like responses.
1-1. The Role in NLP, Machine Translation, and LLM Development
Text annotation is a foundational process in the field of natural language processing, supporting tasks such as text classification, named entity recognition, and relation extraction. Furthermore, in recent large language models (LLMs), it is utilized as training and evaluation data, influencing the accuracy of the models and the quality of their outputs. In the field of machine translation, it helps achieve more natural and accurate translation results through the preparation of parallel corpora and the standardization of terminology.
1-2. Differences from Image Annotation and Speech Annotation
Depending on the target data, annotation includes not only text but also image annotation and audio annotation. Image annotations, such as object detection, and audio annotations, such as language identification and audio event detection, often have relatively clear correct answers and tend to be less influenced by context. On the other hand, text has a wide range of interpretations and depends on surrounding context and cultural background, making annotation more challenging.
2. Why is Text Annotation Important?
The reason why text annotation is considered important is that AI models learn based on data created through text annotation. Because language allows for a wide range of interpretations, it is difficult to correctly recognize meaning and intent from plain text alone. By supplementing information such as emotions, intent, and context through text annotation, the data can be properly understood and learned. Therefore, it can be said that the quality of annotation directly affects the performance of AI models.
2-1. The Relationship with Fine-tuning and RAG
Text annotation is closely related to fine-tuning and RAG (Retrieval-Augmented Generation). In fine-tuning, the model’s output and behavior are controlled by using training data created through text annotation. For example, by learning data pairs of “instructions” and “appropriate responses,” a generative AI can understand what kind of response is desirable.
On the other hand, in RAG, text annotation is utilized in the preprocessing of the data to be searched. For example, by attaching metadata such as category, version, confidentiality classification, and document title, it becomes possible to perform appropriate information retrieval according to the conditions. If the data quality is low, it can lead to inappropriate search results, so text annotation plays a role in supporting the overall accuracy of the system.
3. Main Types of Text Annotation
There are mainly the following types of text annotation.
3-1. Named Entity Recognition (NER)
Extract named entities such as personal names, organization names, place names, and dates from the text and assign labels. This enables AI to recognize important information within the text, such as named entities.
3-2. Part-of-Speech Tagging (POS Tagging)
Assign parts of speech such as nouns, verbs, and adjectives to each word in the sentence. By identifying parts of speech, the sentence structure becomes clearer, which is utilized in syntactic analysis, improving search accuracy, machine translation, and more.
3-3. Sentiment Analysis (Sentiment Annotation)
Classify emotions behind utterances or sentences, such as positive, negative, or neutral. This is used in customer review analysis, chat log analysis, and helps in understanding user sentiment trends.
3-4. Intent Recognition (Intent Annotation)
Classifies the purpose or intent of utterances such as requests, questions, and suggestions. It is used in automating customer support and chatbots.
3-5. Relation Extraction
Extracts the relationships between entities within a sentence. While named entity recognition identifies the "targets," relation extraction explicitly clarifies the relationships between them, which is utilized in knowledge graph construction and information extraction.
4. General Workflow of Text Annotation
Text annotation proceeds through the following process.
1. Clarification of Purpose
Organize what you want to achieve with the AI model and clarify the data usage and tasks.
2. Guideline Design
Define labels, decision criteria, accuracy requirements, etc., and document them as work specifications.
3. Annotator Education and Training
Share guidelines and work procedures, aiming for annotators to be able to make autonomous judgments. If possible, conduct exercises and provide feedback using sample data to align understanding.
4. Annotation Work
The actual annotation work begins. During task progress, manage progress and respond to inquiries that arise during the work.
5. Review and Correction
Check the work results and correct any deficiencies or errors.
6. Quality Check and Feedback
Evaluate the quality and consistency of the work results, and analyze trends in mistakes. Based on these results, improve the guidelines and provide retraining to annotators as needed.
Related blog: Is Annotation Possible with ChatGPT? Follow-up — Attempting Tagging with the Latest ChatGPT in 2025
5. Common Challenges and Solutions in Text Annotation
The following challenges may arise in text annotation.
5-1. Variability Due to Ambiguity in Judgment Criteria
If the guidelines are insufficient, each annotator may interpret them differently, potentially assigning different labels to the same data. This can compromise quality and consistency.
To prevent such variability, it is essential to establish guidelines with clear criteria. For example, when extracting named entities, the guidelines should specify in detail, including concrete examples, prohibited cases, and exceptions, how far to cover abbreviations, common names, and generic terms beyond the official names. By continuously incorporating questions that arise during the work, the guidelines can be operated in a way that reflects the actual situation.
5-2. Balancing Scale Expansion and Quality Maintenance
When increasing the number of annotators to handle large volumes of data, quality tends to decline due to insufficient training and differences in understanding. Additionally, the review workload also increases, which can reduce overall efficiency.
As a countermeasure, it is important to verify annotators’ understanding and aptitude by having them work on sample data in advance and assign tasks according to their skill levels. Furthermore, starting actual work gradually with small amounts of data helps significantly reduce the risk of major quality degradation. Continuous review and feedback also deepen annotators’ understanding and stabilize quality.
5-3. Issues of Security and Data Management
When handling data that includes confidential or personal information, improper access management or operational errors can lead to serious risks such as information leaks.
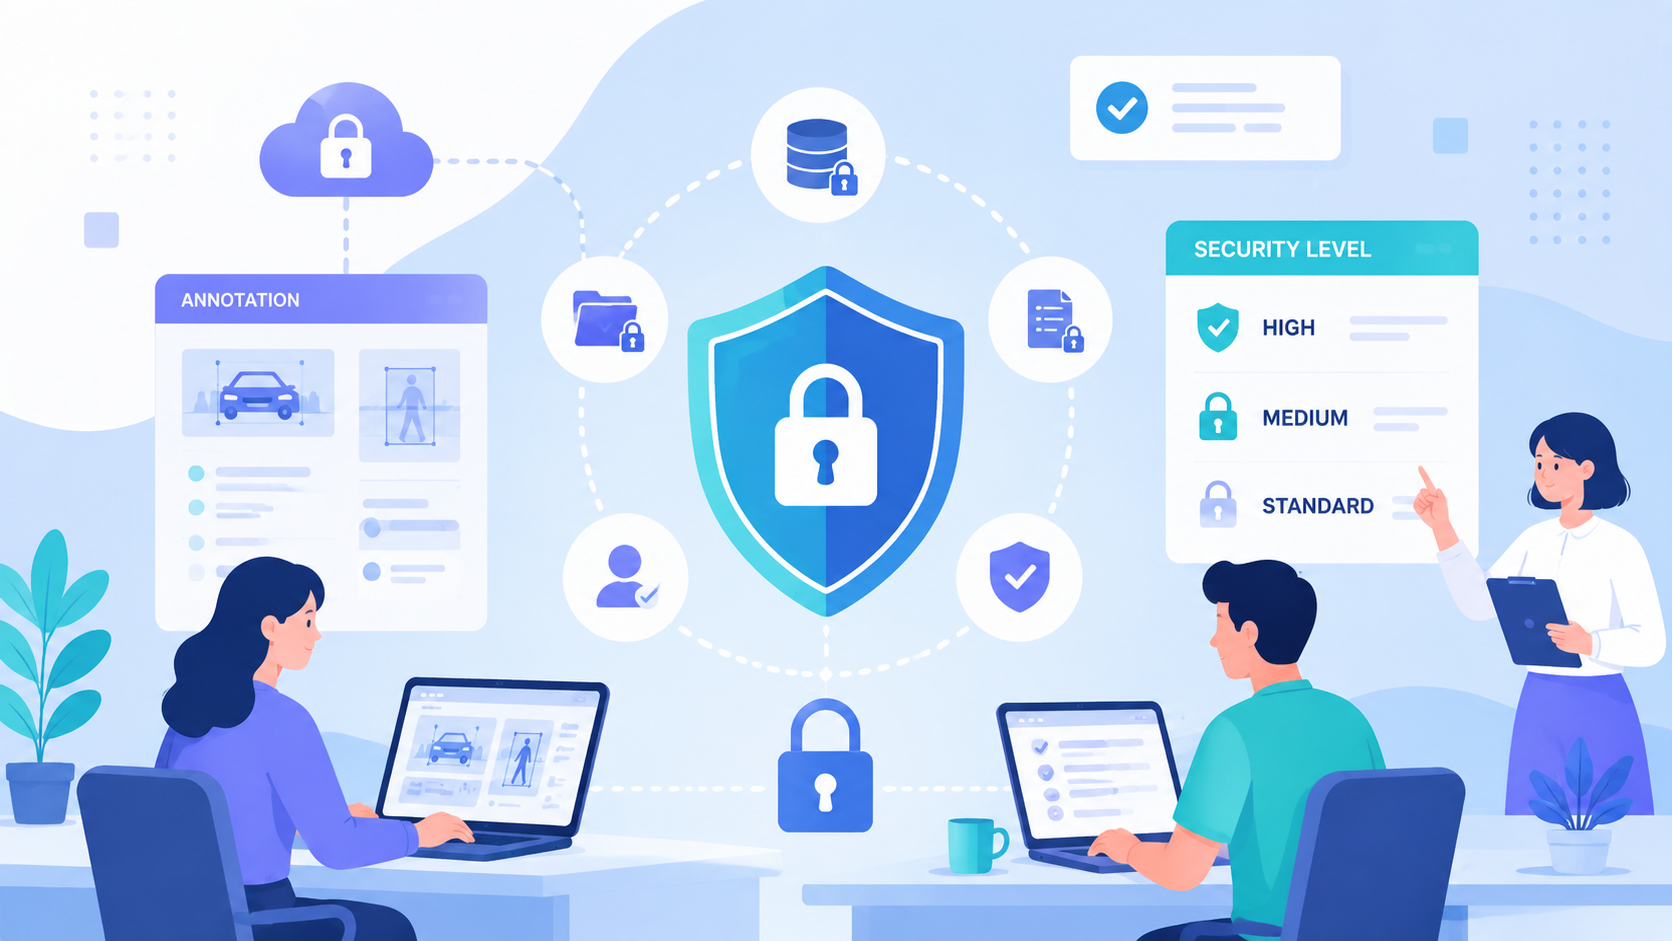
To prevent this, measures such as minimizing access permissions, restricting data removal, and managing logs are required. It is also important to establish operational rules and provide training. When high security is needed, setting up a dedicated work environment (such as a security room) is also effective.
6. Human Science Support for Text Annotation
Over 48 million pieces of training data created
At Human Science, we participate in AI model development projects across a wide range of industries, starting with natural language processing and extending to medical support, automotive, IT, manufacturing, and construction. We have a proven track record of direct business dealings with many companies, including GAFAM. Additionally, we have provided over 48 million pieces of high-quality training data for AI development projects. From small-scale projects to large long-term projects with a team of 150 annotators, we handle various types of training data creation, data labeling, and data structuring regardless of the industry.
Resource management without crowdsourcing
At Human Science, we do not use crowdsourcing. Instead, projects are handled by personnel who are contracted with us directly. Based on a solid understanding of each member's practical experience and their evaluations from previous projects, we form teams that can deliver maximum performance.
Supports not only curation and annotation but also the creation and structuring of generative AI LLM datasets
In addition to labeling for data organization and annotation for identification-based AI systems, we also support the structuring of document data for generative AI and LLM RAG construction. Since our founding, we have been engaged in manual production as a main business and service, and we provide optimal solutions leveraging our unique know-how and deep understanding of various document structures.
Secure room available on-site
Within our Shinjuku office at Human Science, we have secure rooms that meet ISMS standards. Therefore, we can guarantee security, even for projects that include highly confidential data. We consider the preservation of confidentiality to be extremely important for all projects. When working remotely as well, our information security management system has received high praise from clients, because not only do we implement hardware measures, we continuously provide security training to our personnel.
Reference link: Text Annotation Service





 Return to the top of the page
 +81 35-321-3111[Tokyo Headquarters]
 Contact Us
 Request for Information
 TOP
 SITE MENU